We're Coming Out of Stealth Mode
After months of hard work, we’re coming out of stealth today! Welcome to join us to build AI agents democratizing algorithms -> Hiverge.ai.
Read more...
R&D Engineer • OpenSource Enthusiast • Cat Owner • Sports Fan ⚽️ 🏀 🥊
After months of hard work, we’re coming out of stealth today! Welcome to join us to build AI agents democratizing algorithms -> Hiverge.ai.
Read more...Working on system optimization these days, joined a lot of meetings and talked a lot with the potential customers, also questioned a lot by them. Most of them, or even all of them, show great interest in the optimization solution, who can reject the idea of optimization?
Read more...I joined DaoCloud in July 7th, 2021, almost 4 years ago, it’s an amazing journey for me I have to say. I’ve learned a lot, experienced a lot, and grown a lot during this period of time. I am really grateful for all the support and trust DaoCloud has given me, or I can not be who I am today.
Read more...With the growing demand for heterogeneous computing power, Chinese users are gradually adopting domestic GPUs, especially for inference. vLLM, the most popular open-source inference project, has drawn widespread attention but does not support domestic chips.Chinese inference engines are still developing in functionality, performance, and ecosystem. In this session, we’ll introduce how to adapt vLLM to support domestic GPUs,enabling acceleration features like PageAttention, Continuous Batching, and Chunked Prefill. We’ll also cover performance bottleneck analysis and chip operator development to maximize hardware potential. Additionally, Kubernetes has become the standard for container orchestration and is the preferred platform for inference services. We’ll show how to deploy the adapted vLLM engine on Kubernetes using the open-source llmaz project with a few lines of code, and explore how llmaz handles heterogeneous GPU scheduling and our practices for monitoring and elastic scaling.
Read more...Inference workloads are becoming increasingly prevalent and vital in Cloud Native world. However, it’s not easy, one of the biggest challenges is large foundation model can not fit into a single node, like llama 3.1-405B or DeepSeek R1, which brings out the distributed inference with model parallelism, again, make serving inference workloads more complicated.
Read more...Just finished the KubeCon EU 2025 and will end my vocation tomorrow, I’m going to write down something to summarize my KubeCon trip.
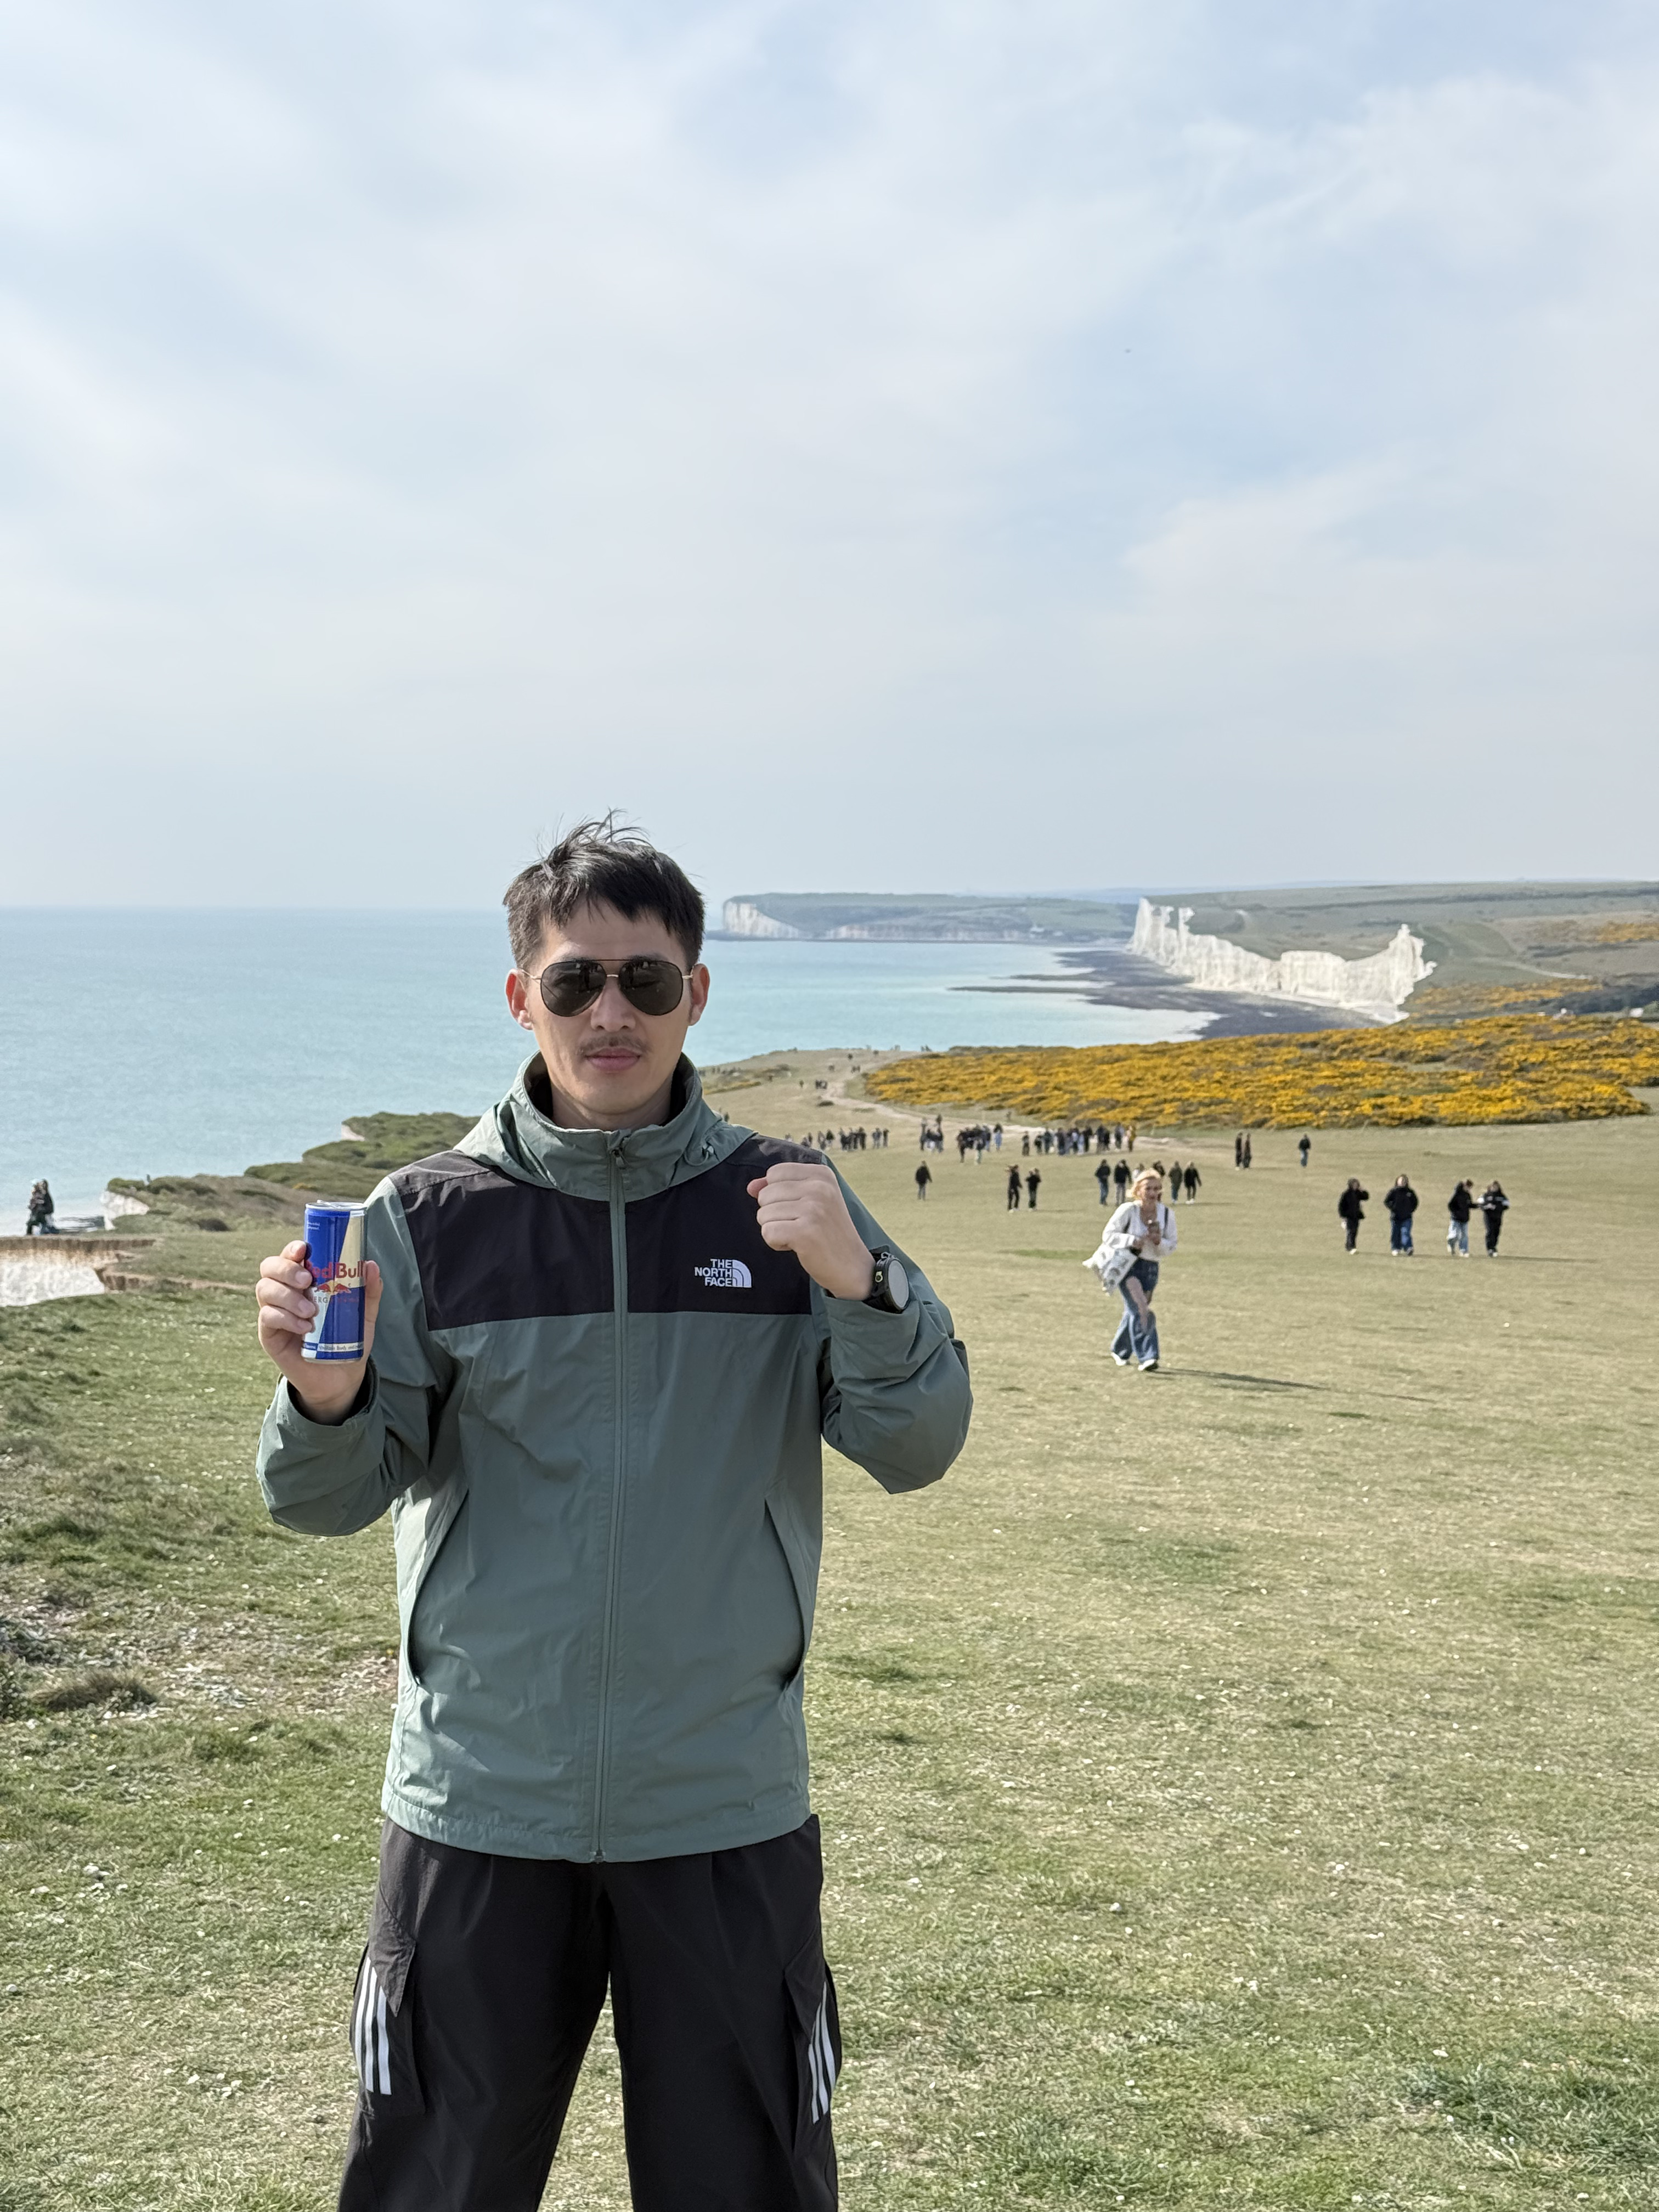
Read more...Hiking in the South of England.
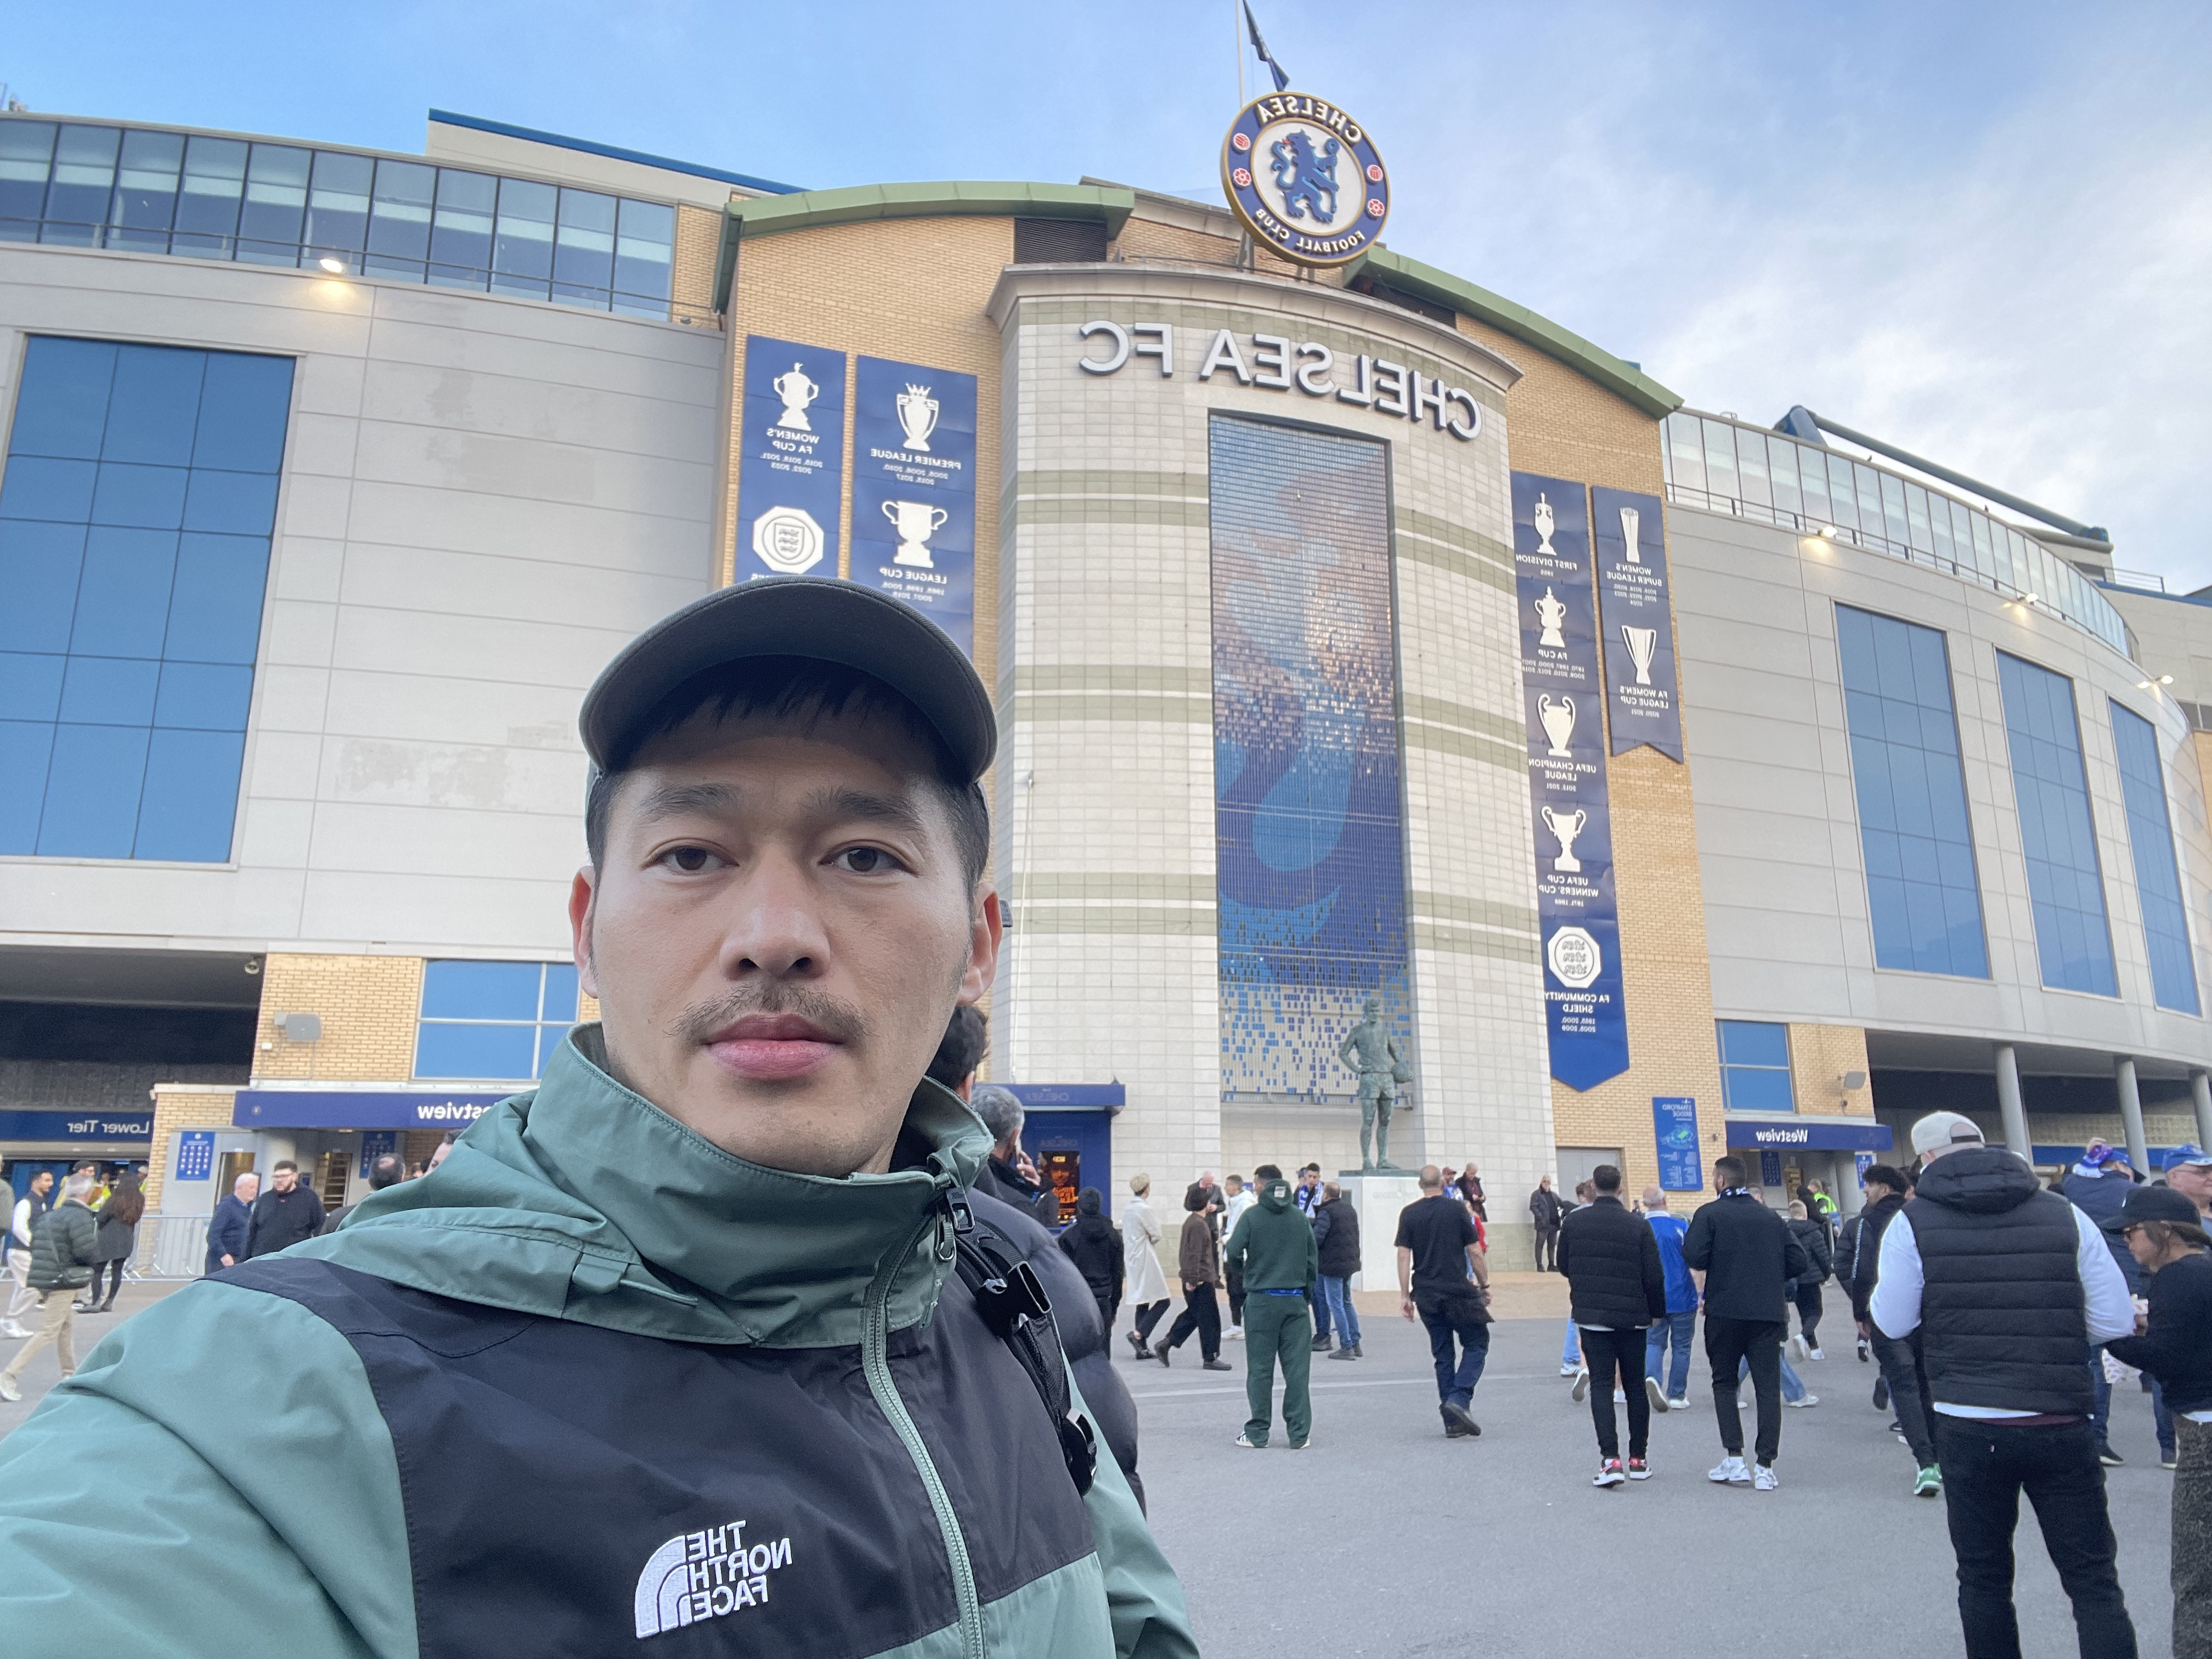
Stamford Bridge.
Inference workloads are becoming increasingly prevalent and vital in Cloud Native world. However, it’s not easy, one of the biggest challenges is large foundation model can not fit into a single node, which brings out the distributed inference with model parallelism, again, make serving inference workloads more complicated.
Read more...Emirates Stadium.